Computer Vision · Robotics
Fine-Grained Vision and ROS2 Robot Deployment
A collaborative deployment-focused computer-vision case study on recovering classifier performance after robot-camera domain shift.
Collaborative academic project · team-level results clearly labelled
Before adaptation
2.38%
After adaptation
95.24%
Reported endpoint comparison
Measured team-level robot-image accuracy before and after deployment-specific adaptation.
Scope
Role and problem
My role: Collaborative group project. My portfolio contribution focuses on robot-camera evaluation, adaptation analysis, and the deployment results I can defend.
A classifier trained on cleaner image data degraded sharply on robot-camera inputs. Lighting, viewpoint, scale, framing, and background conditions changed enough to expose a deployment gap that headline test accuracy concealed.
Architecture
System flow
Curated image dataset
Transfer-learning baseline
Robot-camera capture
Domain-shift diagnosis
Targeted augmentation
Deployment-specific fine-tuning
Confidence-aware ROS2 action mapping
Results and scope
Public record
90.69%
21-class ResNet50 accuracy
Team-level fine-grained classification result across 21 pasta subclasses.
2.38% → 95.24% · n≈42
Robot-image accuracy recovery
Reported figures are mathematically consistent with 1/42 → 40/42; the public camera-image folder contains 42 files. Conditional 95% Wilson intervals: 0.42–12.32% and 84.21–98.68%. Evaluation membership and labels are not independently verified.
3 classes
Reported deployment scope
Project artifacts report fettuccine, fusilli, and penne for the robot-camera phase; the public 42-image folder does not preserve a ground-truth class-balance manifest.
Shared here: The public repository exposes the 42 robot-camera images. The endpoint percentages are consistent with 1/42 and 40/42, and the repository contains 42 robot-camera images; without predictions, ground-truth labels, or a split manifest the denominator is a corroborated inference, not an independently reproduced score.
Figures and supporting evidence
Published charts and screenshots documenting the work, with direct source links where available.
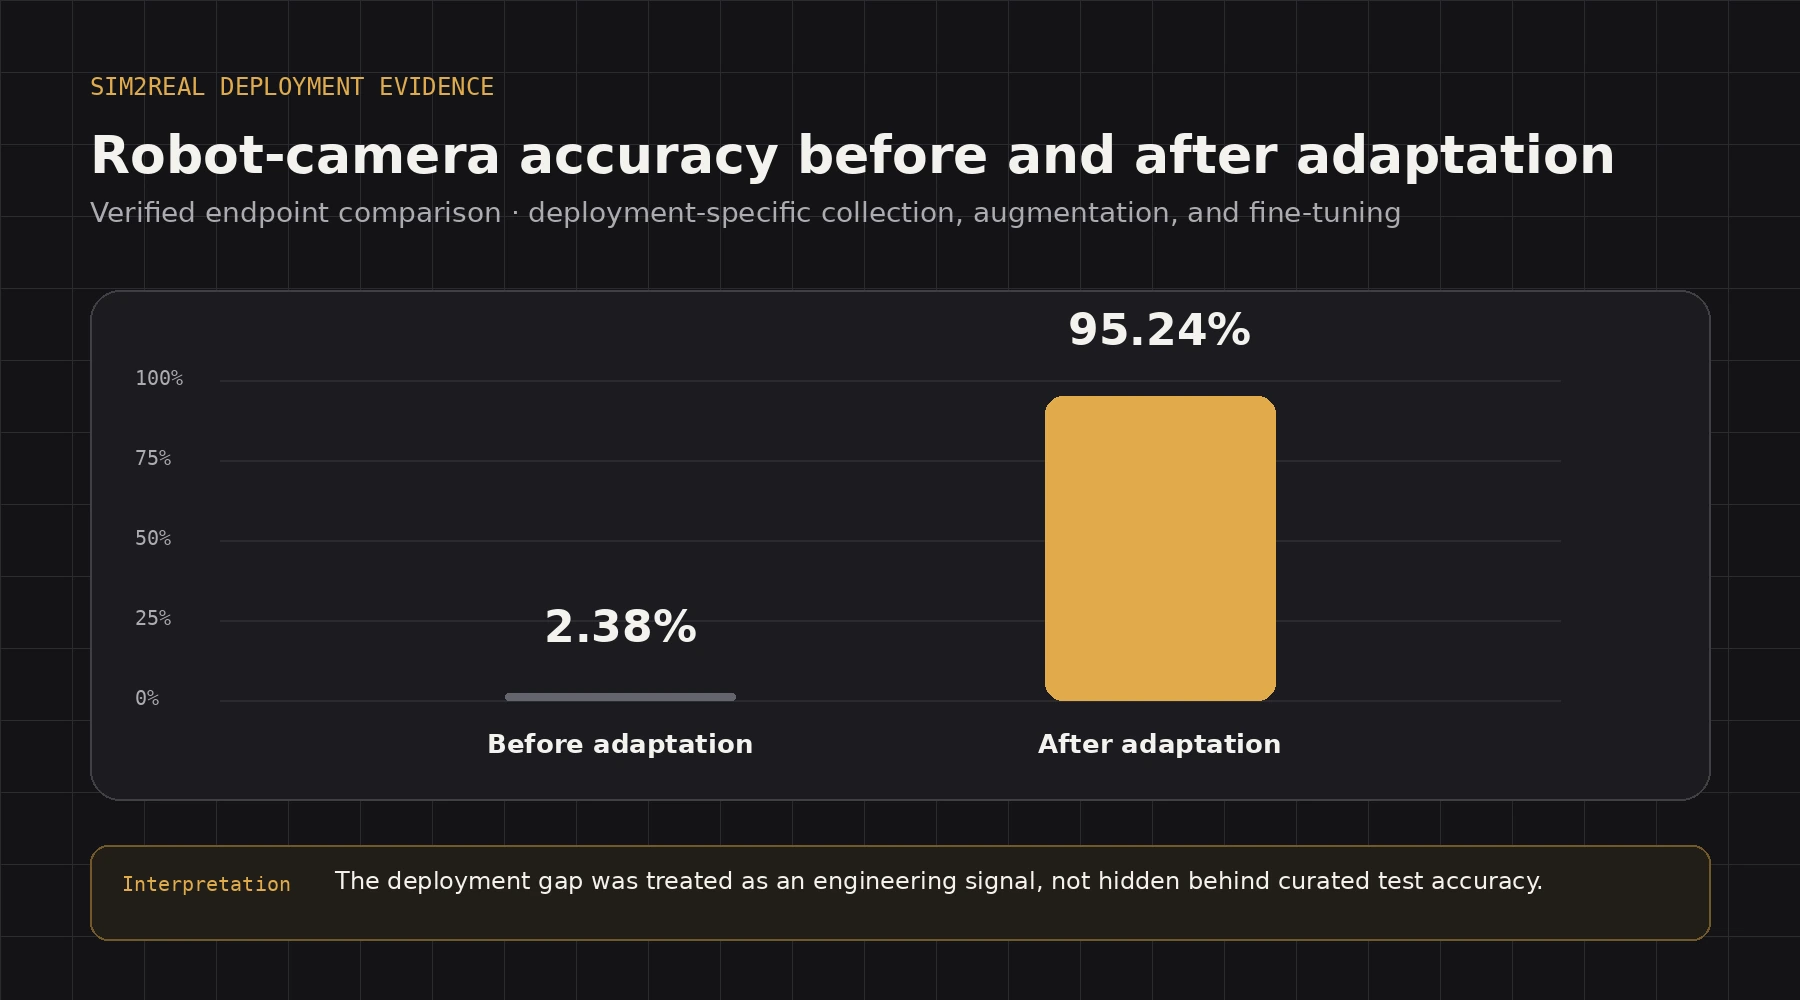
Robot-image accuracy before and after adaptation
Reported collaborative endpoint comparison: 2.38% → 95.24%; 1/42 → 40/42 is the count reconstruction consistent with the 42 public robot-camera image files, not a separately rerun evaluation.
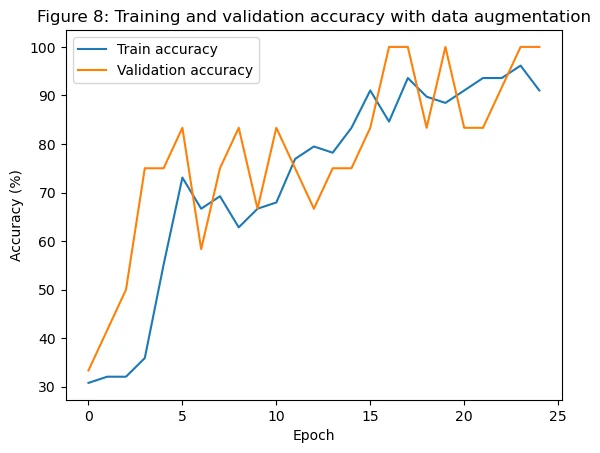
Robot fine-tuning accuracy with augmentation
Exported from the executed notebook: training and validation accuracy across the robot-image fine-tuning run with augmentation.
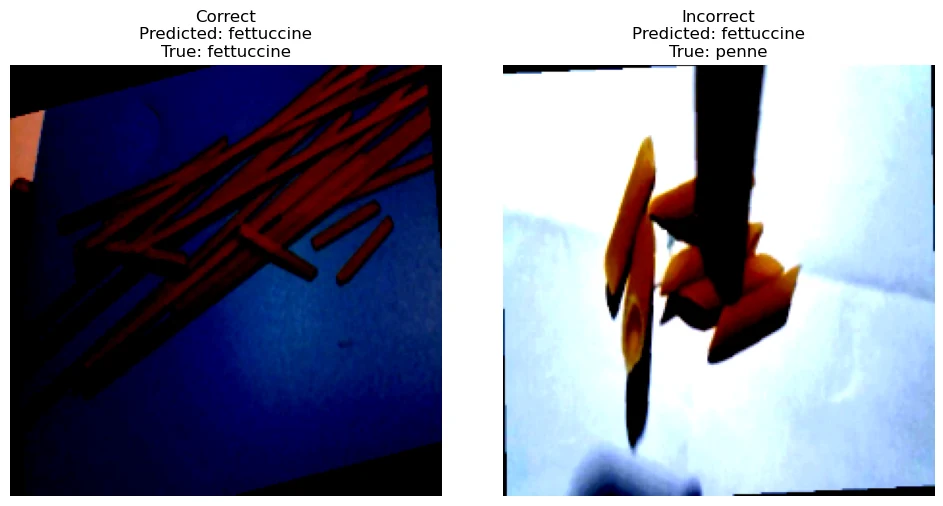
Robot-camera prediction examples
Exported from the executed notebook: representative correct and incorrect predictions under deployment conditions.
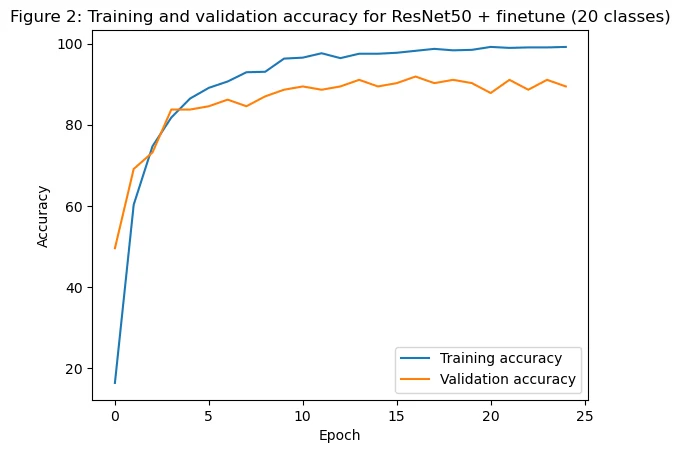
Twenty-one-class ResNet50 training accuracy
Exported from the executed notebook: training and validation accuracy for the broader fine-grained classifier.
Robot recognition and navigation demo
Collaborative Group 15 robot-deployment recording showing the camera-to-action workflow in operation.
Inspect the work
Contribution
- Contributed to the collaborative Phase 3 deployment workflow and the evaluation of robot-camera domain shift.
- Documented how targeted augmentation and fine-tuning changed the deployment result.
- Present team-level metrics with collaborative attribution.
Lessons
- Domain shift should be designed for from the start, not patched at the end.
- A deployment metric can reveal a failure that a curated test set hides.
- Physical actions require explicit confidence boundaries.
Limitations
- The reported metrics are collaborative team-level outcomes.
- The public folder contains 42 robot-camera images, but it does not establish that these were precisely the held-out test items. Ground-truth labels, predicted labels, class balance, and the split-generation record are not published, so the reported accuracies are not independently reproducible.
- The reported deployment phase covers three pasta classes rather than the full twenty-one-class classifier, so the 95.24% result must not be read as a 21-class deployment benchmark.
Stack
- ROS2
- PyTorch
- ResNet50
- Transfer Learning
- Data Augmentation
- Sim2Real