NLP · Semantic Retrieval
RedditPulse: Semantic Retrieval and Grounded Insight Platform
A collaborative NLP and retrieval case study on measuring semantic-search quality before treating generated insights as useful.
Collaborative academic prototype · verified evaluation outputs
Precision@5
0.68
Recall@5
0.68
Embedding size
384d
Verified retrieval metrics
Measured evaluation results from the collaborative prototype.
Scope
Role and problem
My role: Collaborative academic project. My contribution covers retrieval evaluation, dashboard workflow, and published metrics with team attribution.
Public discussions are noisy, high-volume, and difficult to inspect with keyword search alone. The system needed an evidence-first retrieval layer before generated summaries could be treated as useful.
Architecture
System flow
Reddit collection
Text cleaning and metadata
Sentiment analysis
Topic detection
Sentence-transformer embeddings
FAISS retrieval
Top-k evaluation
Grounded insights
Streamlit dashboard
Results and scope
Public record
1,989
Filtered posts
Collaborative dataset after collection and filtering.
1,588
Comments
Discussion context across 10 subreddits.
P@5 = 0.68 · R@5 = 0.68
Semantic retrieval quality
Verified in the public evaluation JSON using 384-dimensional embeddings and FAISS. The judged-query count is not preserved in that export.
Shared here: The retrieval metrics are present in the repository evaluation JSON. The file reports P@5 = 0.68 and R@5 = 0.68, but does not preserve the number of judged evaluation queries, so no query-level n is invented.
Figures and supporting evidence
Published charts and screenshots documenting the work, with direct source links where available.
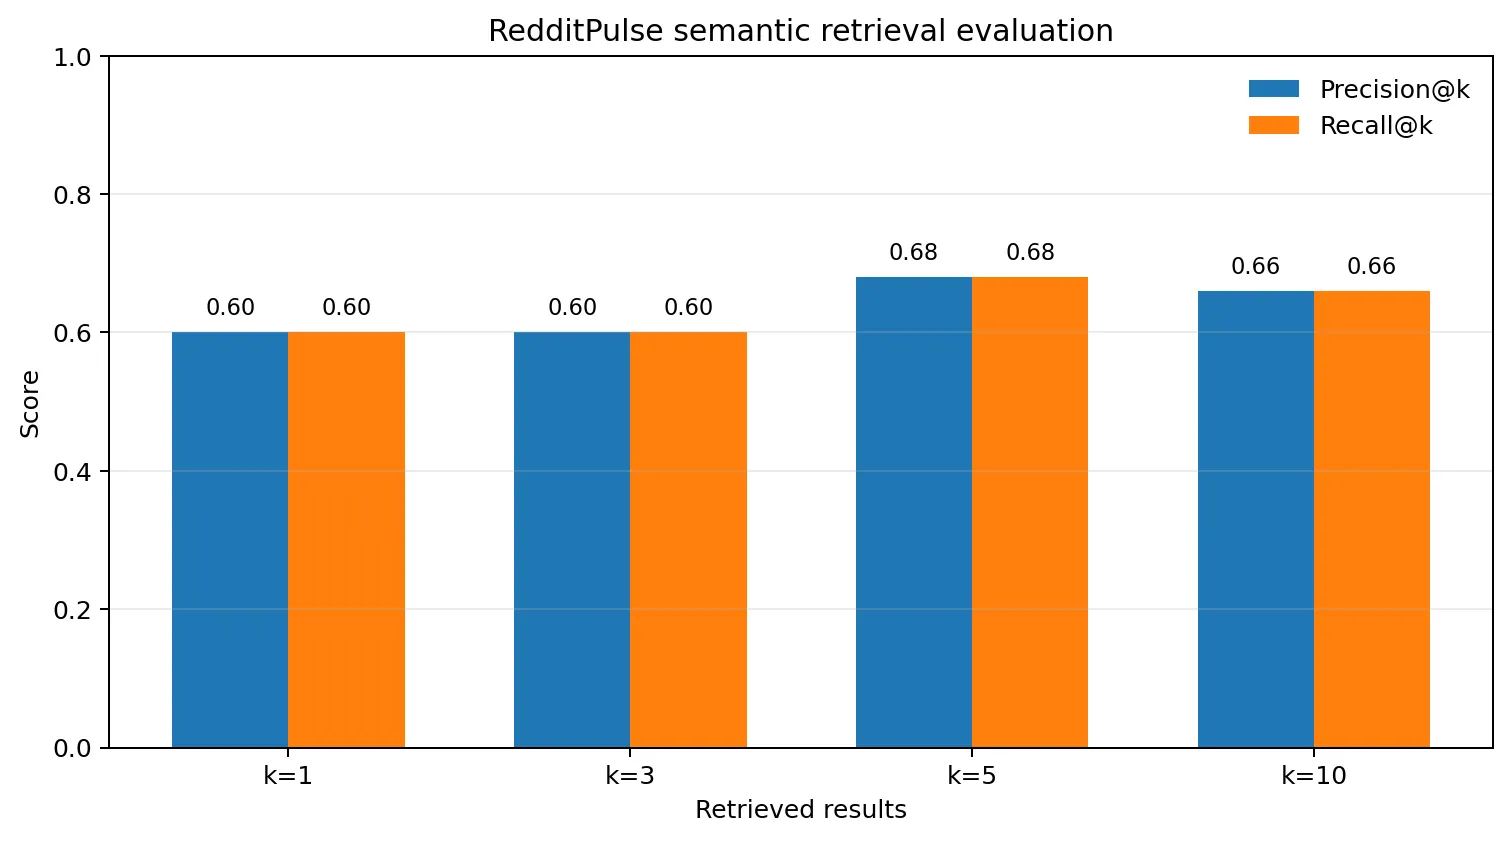
Semantic retrieval evaluation
Generated from the project evaluation JSON: Precision@k and Recall@k across the published retrieval cut-offs.
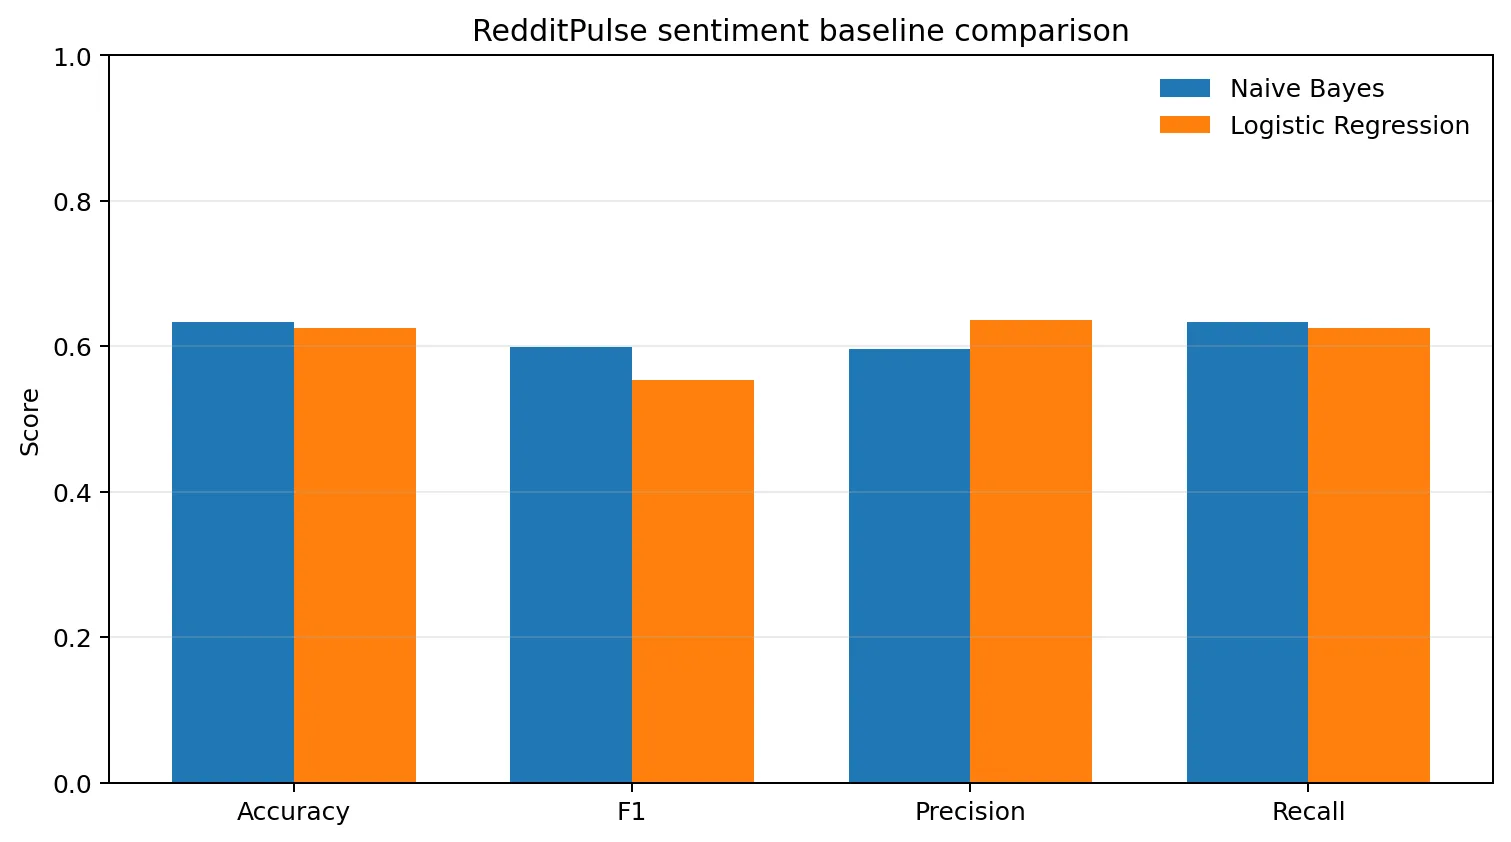
Sentiment baseline comparison
Generated from the project evaluation JSON: Naive Bayes and Logistic Regression baseline metrics.
RedditPulse live dashboard
Interactive public interface for sentiment analysis, topic exploration, and semantic retrieval.
Open dashboardInspect the work
Contribution
- Contributed to the collaborative platform and documented the retrieval-evaluation path, public metrics, and dashboard workflow.
- Keep generated insight claims grounded in measured retrieval quality.
- Present the team-level prototype with collaborative attribution.
Lessons
- Retrieval quality should be evaluated before generation is celebrated.
- TF-IDF remains a valuable baseline even when dense retrieval is added.
- Interactive interfaces are most useful when they expose retrieval context, not only generated summaries.
Limitations
- The metrics and evaluation charts describe the collaborative academic prototype.
- The public evaluation JSON preserves aggregate retrieval metrics but not the number of judged retrieval queries, so uncertainty around those metrics cannot be reconstructed from the public export.
- The public Streamlit dashboard is an interactive research prototype, not a production service; the metrics should not be generalised beyond the stated dataset and retrieval settings.
Stack
- Python
- NLP
- RoBERTa
- Sentence Transformers
- FAISS
- RAG
- Streamlit